1. OpenSearch at a glance #
An open source search and analytics engine.
Overview #
OpenSearch is a distributed search and analytics engine built on Apache Lucene, with its console OpenSearch Dashboards. It serves application search, log analytics, observability, security and, increasingly, vector search. All its components are published under the Apache 2.0 license.
Its history with Elasticsearch #
In 2021, Elastic moved Elasticsearch and Kibana away from the Apache 2.0 license. AWS and contributors then created OpenSearch from the last Apache 2.0 versions (7.10). Since 2024, the project has been hosted by the OpenSearch Software Foundation, within the Linux Foundation. Elastic in turn added an AGPL option to its licenses in 2024.
| Point | OpenSearch | Elasticsearch |
|---|---|---|
| License | Apache 2.0 | Elastic License, SSPL or AGPL, at your choice |
| Security, alerting, ISM | Included plugins | Depends on the subscription |
| Index lifecycle | ISM (_plugins/_ism) | ILM |
| Languages | DSL, SQL, PPL | DSL, SQL, ES|QL |
| Console | OpenSearch Dashboards | Kibana |
The two projects have diverged. Concepts and much of the API remain common, but do not assume that a configuration, client or plugin is compatible: check. Some official Elasticsearch clients refuse to connect to OpenSearch; use the OpenSearch clients.
2. Concepts #
Indexes, shards and replicas.
Vocabulary #
| Concept | Meaning |
|---|---|
| Document | A JSON object |
| Index | A collection of documents |
| Shard | A piece of an index, which is a Lucene index |
| Primary / replica | The original and its copy |
| Mapping | The type of each field |
| Cluster manager | Node managing cluster state: the former “master” |
The cluster #
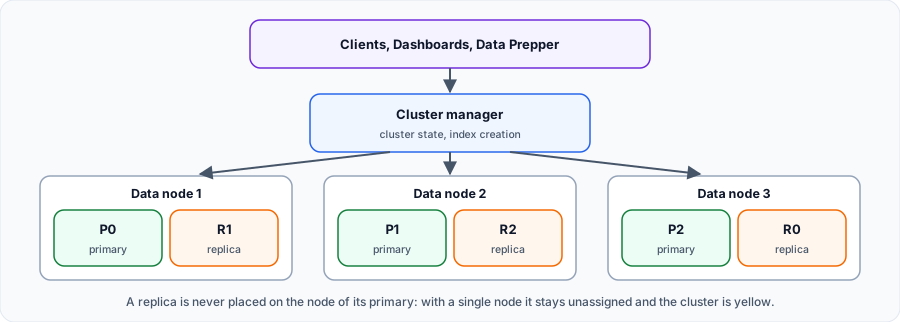
| State | Meaning | What to do? |
|---|---|---|
| green | All shards are assigned | Nothing |
| yellow | Some replicas are unassigned | Normal with a single node; otherwise, add a node |
| red | Some primaries are missing | Urgent: data is unavailable |
3. Components #
What surrounds the engine.
The ecosystem #
| Component | Purpose |
|---|---|
| OpenSearch Dashboards | Exploration, visualizations, administration |
| Data Prepper | Collection and transformation, recommended for ingestion |
| Included plugins | Security, Alerting, Index Management, SQL/PPL, k-NN, Observability, Anomaly Detection… |
The official 3.9 archive ships these plugins and its own JDK; list them with GET _cat/plugins.
My progress
Sign in to track your progress and take notes. Sign in
Recommended Articles
Feeding OpenSearch: ingest pipelines and Data Prepper
Transform data with ingest pipelines, collect with Data Prepper, receive OTLP and avoid the dynam...
OpenSearch Dashboards, alerting and observability
Explore data in OpenSearch Dashboards, create alert monitors and discover Trace Analytics, Event ...
OpenSearch in production: ISM, backups, security and best practices
Automate the lifecycle with ISM, back up with snapshots, manage roles and size an OpenSearch clus...
Architecture distribuée Elasticsearch : rôles des nœuds, shards, répliques et allocation
Comprendre le fonctionnement distribué d'Elasticsearch : rôles des nœuds, nœuds master et quorum,...
Installing OpenSearch and OpenSearch Dashboards
Install OpenSearch with Docker Compose or the archive: initial password, vm.max_map_count, demo c...
Indexing and searching in OpenSearch: mapping, DSL, PPL and SQL
Declare an index template, index with bulk, search with the Query DSL, aggregate and query with P...
Performance et capacity planning Elasticsearch : shards, heap, indexation et benchmarks
Dimensionner et optimiser Elasticsearch : taille et nombre de shards, heap JVM, caches, réglages ...
Monitoring et troubleshooting Elasticsearch : santé, shards non assignés, JVM, hot threads et slow logs
Diagnostiquer un cluster Elasticsearch : cluster health et CAT APIs, shards non assignés et alloc...
Bonnes pratiques Elasticsearch : mappings, shards, cycle de vie et exploitation
Bonnes pratiques Elasticsearch : dimensionnement des shards, mappings explicites, templates, ILM,...