1. Archiving to object storage #
The basis for replay.
A well-partitioned S3 destination #
Bucket:               telemetry-archive
Key prefix:           cribl
Partitioning expr.:   `${C.Time.strftime(_time ? _time : Date.now()/1000, '%Y/%m/%d/%H')}/${sourcetype}/${host}`
Data format:          JSON   (or Parquet)
Compression:          gzip
Max file size: 32 MB · Max file open time: 300 s- Partitioning by date then type lets you replay one hour of one log type without reading everything else.
- Parquet (columnar) compresses better and can be queried directly by Cribl Search, Athena or ClickHouse; gzip JSON is the simplest to read back.
- A bucket lifecycle rule (move to cold class, expiry) sets retention and cost.
2. Replaying #
Re-injecting a specific period.
Collector and replay #
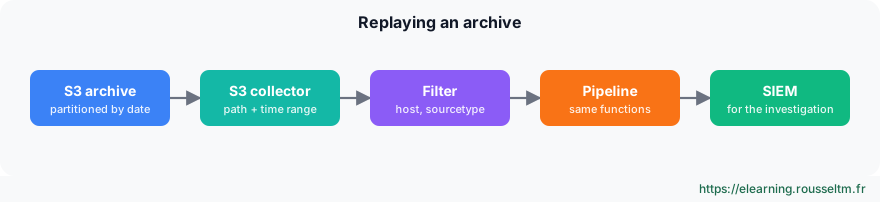
- Create an S3 collector pointing at the archive, with a path matching the partitioning:
/cribl/${_time:%Y}/${_time:%m}/${_time:%d}/${_time:%H}/${sourcetype}/${host}/. - Run it on demand (Run) with the time range and a filter (
host=="srv-42"): Cribl only reads the matching partitions thanks to the path variables. - Replayed events go through routes like any others: add a field (
replayed=true) to route them to the SIEM and tell them apart. - The collector Preview mode shows a sample before running the full collection.
Best practice : Also schedule regular collections (Schedule) for APIs that do not push their data: SaaS audit, inventories, cloud metrics.
3. Cribl Lake and Cribl Search #
Storing and querying without re-ingesting.
Cribl Lake #
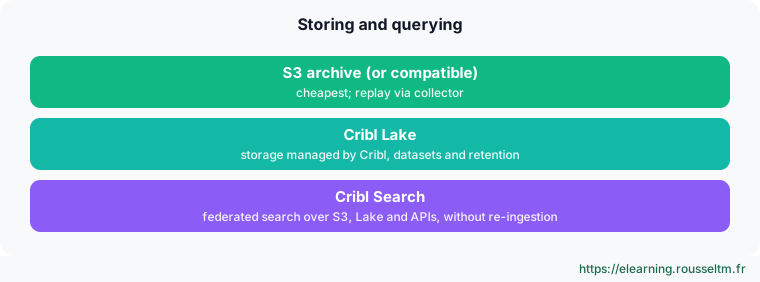
Cribl Lake is managed storage in Cribl.Cloud: you create datasets with their retention, and a Cribl Lake destination writes to them from Stream or Edge, without managing a bucket or format.
Cribl Search #
Cribl Search queries data where it lives: Cribl Lake, S3 buckets and some APIs, with a Kusto-like language (KQL). Since 4.17, a Cribl Search destination also lets you send data to it directly from Stream or Edge.
dataset="archive_fw" action="deny"
| summarize count() by src_ip
| sort by count_ desc
| limit 10
Good to know : The exact syntax and available datasets depend on your Cribl.Cloud workspace: start from the sample queries offered in the UI.
When to use what #
| Need | Solution |
|---|---|
| Keep everything at the lowest cost | S3 archive + lifecycle rules |
| Re-inject a period into the SIEM | S3 collector and replay |
| Find a needle without re-ingesting | Cribl Search |
| Managed storage, no bucket to administer | Cribl Lake |
Commands to know #
Commands to know
C.Time.strftime(_time, '%Y/%m/%d/%H'): partition by hour/${_time:%Y}/${_time:%m}/${_time:%d}/: collector path variablesaws s3 ls s3://archive/cribl/2026/11/17/ --recursive | head: check the archivedataset="…" | summarize count() by host: Cribl Search query
Sources #
Checked in November 2026 (Cribl 4.20): Cribl ships a minor release about every two months, check the release notes before relying on a detail.
My progress
Sign in to track your progress and take notes. Sign in
💬 Questions about this lesson
No questions yet: be the first to ask for help or share your configuration.
Recommended Articles
Cribl: the data pipeline for observability and security
Discover Cribl: why a telemetry data pipeline, the Cribl suite (Stream, Edge, Lake, Search, Cribl...
Reducing, transforming and optimizing volumes with Cribl
Reducing the volume sent to SIEMs and observability tools without losing useful information: Drop...
Sources, destinations and routes in Cribl Stream
Receiving and sending data with Cribl Stream: push, pull, collector and internal sources, event b...
Cribl Stream in production: distributed architecture, persistent queues and monitoring
Taking Cribl Stream to production: Leader, Worker Groups and processes, commit and deploy, scalin...
Automating Cribl: REST API, Packs, Git and Terraform
Managing Cribl as code: REST API (authentication, group paths, commit and deploy), reusable Packs...
Cribl Stream and Edge best practices
Best practices for running Cribl in production: route and pipeline design, naming, performance, c...
Installing and administering Cribl Stream
Installing Cribl Stream with Docker or on Linux, running it as a service, understanding $CRIBL_HO...
Cribl Edge: collecting close to the sources
Deploying Cribl Edge on Linux, Windows and Kubernetes: the agent's role, Fleets and Subfleets, co...
Pipelines and functions: parse, enrich, mask
Building Cribl Stream pipelines: pre-processing, processing and post-processing, the function cat...