1. OpenSearch at a glance #
An open source search and analytics engine.
Overview #
OpenSearch is a distributed search and analytics engine built on Apache Lucene, with its console OpenSearch Dashboards. It serves application search, log analytics, observability, security and, increasingly, vector search. All its components are published under the Apache 2.0 license.
Its history with Elasticsearch #
In 2021, Elastic moved Elasticsearch and Kibana away from the Apache 2.0 license. AWS and contributors then created OpenSearch from the last Apache 2.0 versions (7.10). Since 2024, the project has been hosted by the OpenSearch Software Foundation, within the Linux Foundation. Elastic in turn added an AGPL option to its licenses in 2024.
| Point | OpenSearch | Elasticsearch |
|---|---|---|
| License | Apache 2.0 | Elastic License, SSPL or AGPL, at your choice |
| Security, alerting, ISM | Included plugins | Depends on the subscription |
| Index lifecycle | ISM (_plugins/_ism) | ILM |
| Languages | DSL, SQL, PPL | DSL, SQL, ES|QL |
| Console | OpenSearch Dashboards | Kibana |
The two projects have diverged. Concepts and much of the API remain common, but do not assume that a configuration, client or plugin is compatible: check. Some official Elasticsearch clients refuse to connect to OpenSearch; use the OpenSearch clients.
2. Concepts #
Indexes, shards and replicas.
Vocabulary #
| Concept | Meaning |
|---|---|
| Document | A JSON object |
| Index | A collection of documents |
| Shard | A piece of an index, which is a Lucene index |
| Primary / replica | The original and its copy |
| Mapping | The type of each field |
| Cluster manager | Node managing cluster state: the former “master” |
The cluster #
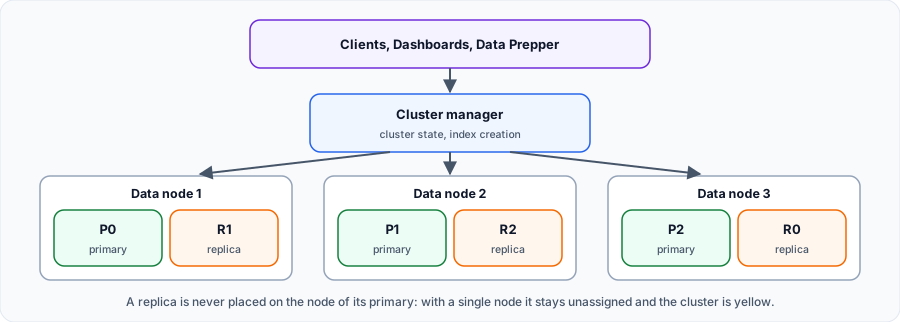
| State | Meaning | What to do? |
|---|---|---|
| green | All shards are assigned | Nothing |
| yellow | Some replicas are unassigned | Normal with a single node; otherwise, add a node |
| red | Some primaries are missing | Urgent: data is unavailable |
3. Components #
What surrounds the engine.
The ecosystem #
| Component | Purpose |
|---|---|
| OpenSearch Dashboards | Exploration, visualizations, administration |
| Data Prepper | Collection and transformation, recommended for ingestion |
| Included plugins | Security, Alerting, Index Management, SQL/PPL, k-NN, Observability, Anomaly Detection… |
The official 3.9 archive ships these plugins and its own JDK; list them with GET _cat/plugins.
My progress
Sign in to track your progress and take notes. Sign in
Recommended Articles
Data streams et templates Elasticsearch : component templates, index templates et séries temporelles
Gérer les données horodatées avec les data streams : index templates et component templates, conv...
Understanding the Elastic Common Schema (ECS)
As always in our consulting engagements, we recommend that companies harmonise and standardise: k...
Cross-cluster search et cross-cluster replication : architectures multi-clusters Elasticsearch
Concevoir des architectures multi-clusters Elasticsearch : clusters distants, cross-cluster searc...
Index Lifecycle Management (ILM) : data tiers, rollover et rétention
Automatiser le cycle de vie des index avec ILM : data tiers hot, warm, cold et frozen, rollover p...
Différences entre Technologies et Services dans Dynatrace
Dans Dynatrace, les concepts de 'Technologie' et de 'Services' aident à organiser et surveiller l...
Dynatrace : Différences entre SQL Modifications, SQL Queries or Procedures, et SQL Transactions
Cet article détaille les différences entre trois concepts essentiels dans l'exécution des instruc...
Understanding the concept of score
The concept of score allows Elasticsearch to rank your documents by relevance during a search.
Ingestion Elasticsearch : Bulk API, ingest pipelines, enrich et reindex
Ingérer et transformer des données dans Elasticsearch : Bulk API, ingest pipelines et processeurs...
Query DSL et agrégations avancées Elasticsearch, avec ES|QL
Écrire des requêtes Elasticsearch avancées : bool, filter et score, nested, function_score et per...