1. Why correlate #
Diagnosis time is the real cost of an incident.
Without and with correlation #
Without correlation, the on-call engineer sees an error spike on a dashboard, searches logs around the same time, guesses which service is at fault, then looks for a trace « that looks similar ». With correlated signals, each step is a click, on data that concerns the same request.

2. Correlation mechanisms #
What needs to be set up.
Overview #
| Link | Mechanism | To check |
|---|---|---|
| All signals of a service | identical resource (service.name, service.version, deployment.environment.name, k8s.pod.name) | same SDK or same variables for all signals; k8sattributes in the Collector |
| Log → trace | trace_id and span_id in every log | OTel appender or added to the JSON format |
| Metric → trace | exemplars with trace_id | exemplars enabled in the SDK and stored by the backend (Prometheus --enable-feature=exemplar-storage) |
| Trace → metrics | span metrics and service graph computed from spans | spanmetrics, servicegraph connectors or Tempo's metrics generator |
| Trace → profile | samples tagged with the span_id | profiling SDK with a span processor |
| Business context | propagated baggage (tenant.id, shop.customer.tier) | processor that copies baggage into attributes |
A shared resource #
# Les mêmes variables pour tous les signaux d'un service
export OTEL_SERVICE_NAME=checkout
export OTEL_RESOURCE_ATTRIBUTES=service.namespace=shop,service.version=1.4.0,deployment.environment.name=production
export OTEL_TRACES_EXPORTER=otlp OTEL_METRICS_EXPORTER=otlp OTEL_LOGS_EXPORTER=otlp
Common mistake: If traces saycheckoutand logs saycheckout-api, no automatic navigation works. The service name is the key to all correlation.
3. Configuring Grafana #
Links between data sources.
Provisioning data sources #
apiVersion: 1
datasources:
  - name: Tempo
    type: tempo
    uid: tempo
    url: http://tempo:3200
    jsonData:
      tracesToLogsV2:
        datasourceUid: loki
        filterByTraceID: true
        spanStartTimeShift: -5m
        spanEndTimeShift: 5m
      tracesToMetrics: { datasourceUid: prometheus }
      tracesToProfiles: { datasourceUid: pyroscope, profileTypeId: "process_cpu:cpu:nanoseconds:cpu:nanoseconds" }
      serviceMap: { datasourceUid: prometheus }
  - name: Loki
    type: loki
    uid: loki
    url: http://loki:3100
    jsonData:
      derivedFields:
        - { name: TraceID, matcherRegex: '"trace_id":"(\w+)"', url: "$${__value.raw}", datasourceUid: tempo }
  - name: Prometheus
    type: prometheus
    uid: prometheus
    url: http://prometheus:9090
    jsonData:
      exemplarTraceIdDestinations: [{ name: trace_id, datasourceUid: tempo }]
The typical journey #
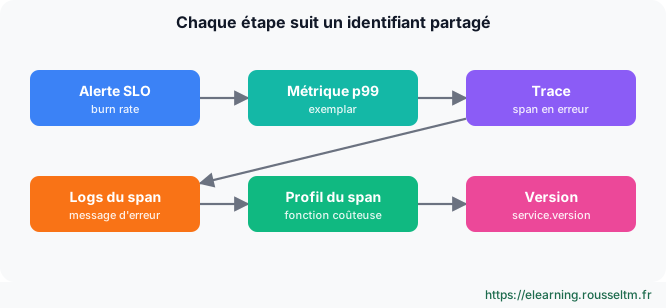
- The burn rate alert fires on the latency SLO.
- The p99 latency panel shows exemplars: click the highest one.
- The trace opens: the
paymentspan lasts 2 s and ends in error. - « Logs for this span » shows the
connection pool exhaustedlog. - « Profiles for this span » shows the time spent waiting for the pool.
- The version (
service.version) shows the problem appeared with the last deployment.
4. Baggage and business context #
Correlating with the business too.
Using baggage #
from opentelemetry import baggage, context
ctx = baggage.set_baggage("shop.customer.tier", "premium")
token = context.attach(ctx)        # propagé aux services appelés (en-tête baggage)
try:
    appeler_paiement()
finally:
    context.detach(token)
In the SDKs and the Collector, a span processor can copy certain baggage keys into span attributes to filter « all slow traces from premium customers ».
Common mistake: Baggage travels in plain text in HTTP headers, including to third-party services: never put sensitive data in it and filter it when leaving the system.
My progress
Sign in to track your progress and take notes. Sign in
💬 Recent discussions about this course
- Quels attributs utiliser pour nommer mes spans HTTP (semconv) ?✓ solved · 1 reply(ies)
- OpenTelemetry Collector : mes traces arrivent mais pas mes métriques✓ solved · 2 reply(ies)
Ask a question about this lesson →See all discussions about this course
Recommended Articles
Correlating traces, logs, metrics and profiles in Grafana
Link Tempo to logs (Loki), metrics (Prometheus) and profiles (Pyroscope): tracesToLogs, tracesToM...
Profiles, OpenTelemetry's fourth signal: continuous profiling and correlation with traces
Understand OpenTelemetry's new profile signal: continuous profiling, flame graphs, data model and...
Capstone project: the four signals of the OpenTelemetry Demo in the Grafana stack
A capstone project spanning the observability courses: deploy the OpenTelemetry Demo, send metric...
Logs with OpenTelemetry: data model, appenders, correlation and collection
Master the log signal: the LogRecord data model, the Logs Bridge API and appenders (Logback, Log4...
Tempo: generating metrics from traces (service graph, span metrics, exemplars)
Enable Tempo's metrics-generator: service graphs, RED span metrics, remote write to Prometheus or...
Linking traces and profiles: span profiles with Tempo and Pyroscope
Go from a slow trace to the exact CPU profile of that span: span profiles in Go and Java, configu...
OpenTelemetry metrics: instruments, temporality, histograms and exemplars
Master the metric signal: MeterProvider, synchronous and asynchronous instruments (Counter, UpDow...
OpenTelemetry: automatic vs manual instrumentation
Understand the differences between automatic and manual instrumentation with OpenTelemetry, their...
Datadog APM and OpenTelemetry: traces, services and correlation with logs
Instrument applications for Datadog APM (dd-trace, single step instrumentation, OpenTelemetry), u...